 Business
Field note
Measure the work before you automate it
Build an AI pilot around a baseline, a review checklist and a worked cost comparison—so a faster draft does not get mistaken for a better process.
BusinessField note
Build an AI pilot around a baseline, a review checklist and a worked cost comparison—so a faster draft does not get mistaken for a better process.
A model benchmark does not measure your organization’s complete process. Start by observing representative cases from intake through review and completion. Record the work people perform, the time a case waits, and the exceptions that send it back. Keep active effort separate from elapsed time: a faster response and fewer staff minutes can be valuable, but they are different outcomes.
Here is an invented invoice-review example to make the arithmetic concrete. Twenty cases at eight minutes of manual effort each total 160 minutes. Suppose an assisted version takes one minute to prepare and three minutes to review each case, plus 40 minutes of corrections across the batch. That totals 120 minutes, leaving a 40-minute difference before setup, provider fees and maintenance. These are illustrative numbers, not an Ashlr result or a savings forecast.
Quality needs its own acceptance criteria. For this example, require the vendor, invoice number, amount and currency to match the source; require a reviewer to resolve duplicates or ambiguity before approval. Score those checks separately from speed. A draft completed quickly but assigned to the wrong vendor should fail, even if the average processing time improves. Preserve the source reference so the reviewer can inspect the evidence rather than trust a confident explanation.
Anthropic’s engineering guide on evaluations emphasizes clear success criteria, inspection of execution records and maintaining evaluations as systems change. Apply that discipline to the whole handoff. Include difficult cases and previously observed failures, rather than comparing routine automated cases with unusually hard manual ones. Keep a set of cases out of development so repeated tuning does not become the only reason the score looks better.
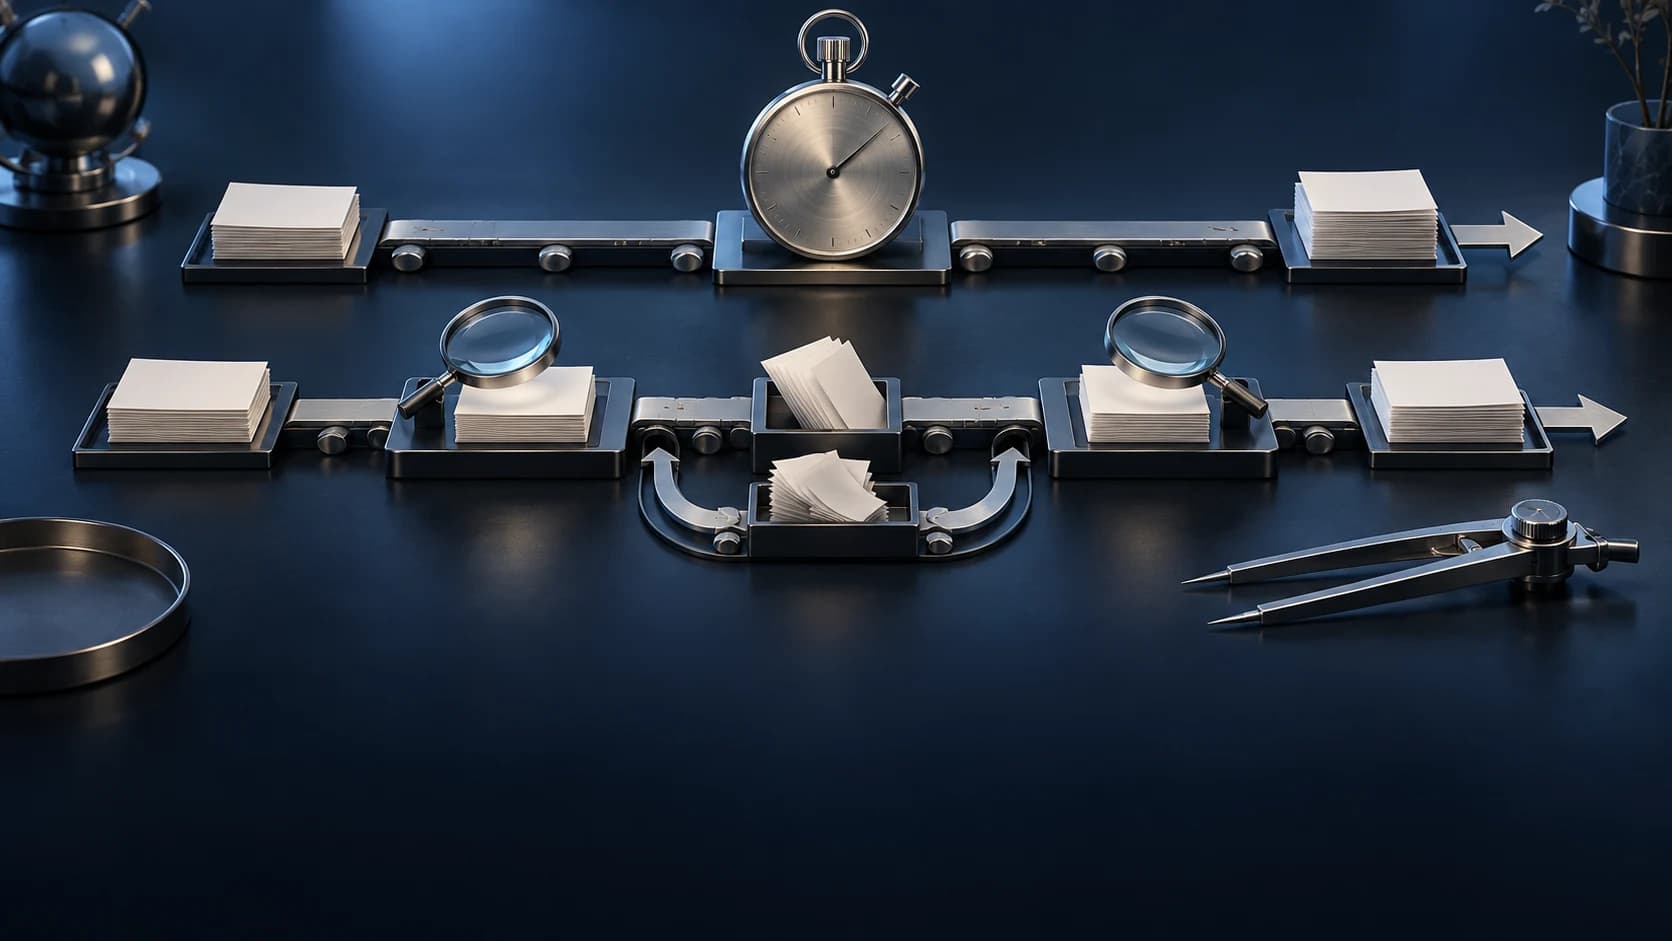
Version the test inputs, prompts, tools and grading rules together. In the invoice example, log preparation, review and correction effort separately and attach the source reference to each extracted field. Compare the existing and proposed process on equivalent cases, with the same acceptance checklist. Inspect surprising passes and failures instead of relying on one aggregate score. If a model-generated grader is used, check its decisions against judgments from qualified reviewers before depending on it. Missing fields, unresolved duplicates and source mismatches should be visible outcomes, not quietly excluded records that make a dashboard look cleaner.
Name an operator who can reject an output and a budget owner who can assess the full cost. For the invented batch, the 40-minute difference is only a starting observation in the example. It does not establish annual savings, staffing reductions or a return on investment. Ask how case complexity, adoption, review effort and ongoing maintenance could change the result. Set a stop condition as well as an expansion condition: repeated material errors or unmanageable review effort should pause the pilot even when generation is fast. A useful decision includes the quality tradeoff, not just the largest favorable number.
Collect a small set of routine cases and difficult exceptions with permission from the people responsible for the data. Define the pass criteria before trying the automation. Record the current effort, then run a limited comparison and review the mistakes with an operator. Treat the first sample as a way to find failure modes and improve the measurement plan; gather broader evidence before predicting organization-wide gains.
Source material behind this field note. Our practical implications are Ashlr’s interpretation.
Field notes explain an engineering or business practice. They are not reports of a new event. Cover artwork is illustrative.
Subscribers to $100, $200, or $500 ChatGPT plans now receive equivalent monthly credits usable with the OpenAI API, following a similar benefit from Anthropic.
 Business
The briefing
AI-generated illustration
OpenAI announced AI-produced results on local smoothing, the Exponential Time Hypothesis and quantum field theory. Experts are now checking them.
 Business
The briefing
AI-generated illustration
Anthropic filed its S-1 for an IPO under the ticker ANT. Share count and price are not set yet. Here is what the filing does and does not tell you.